
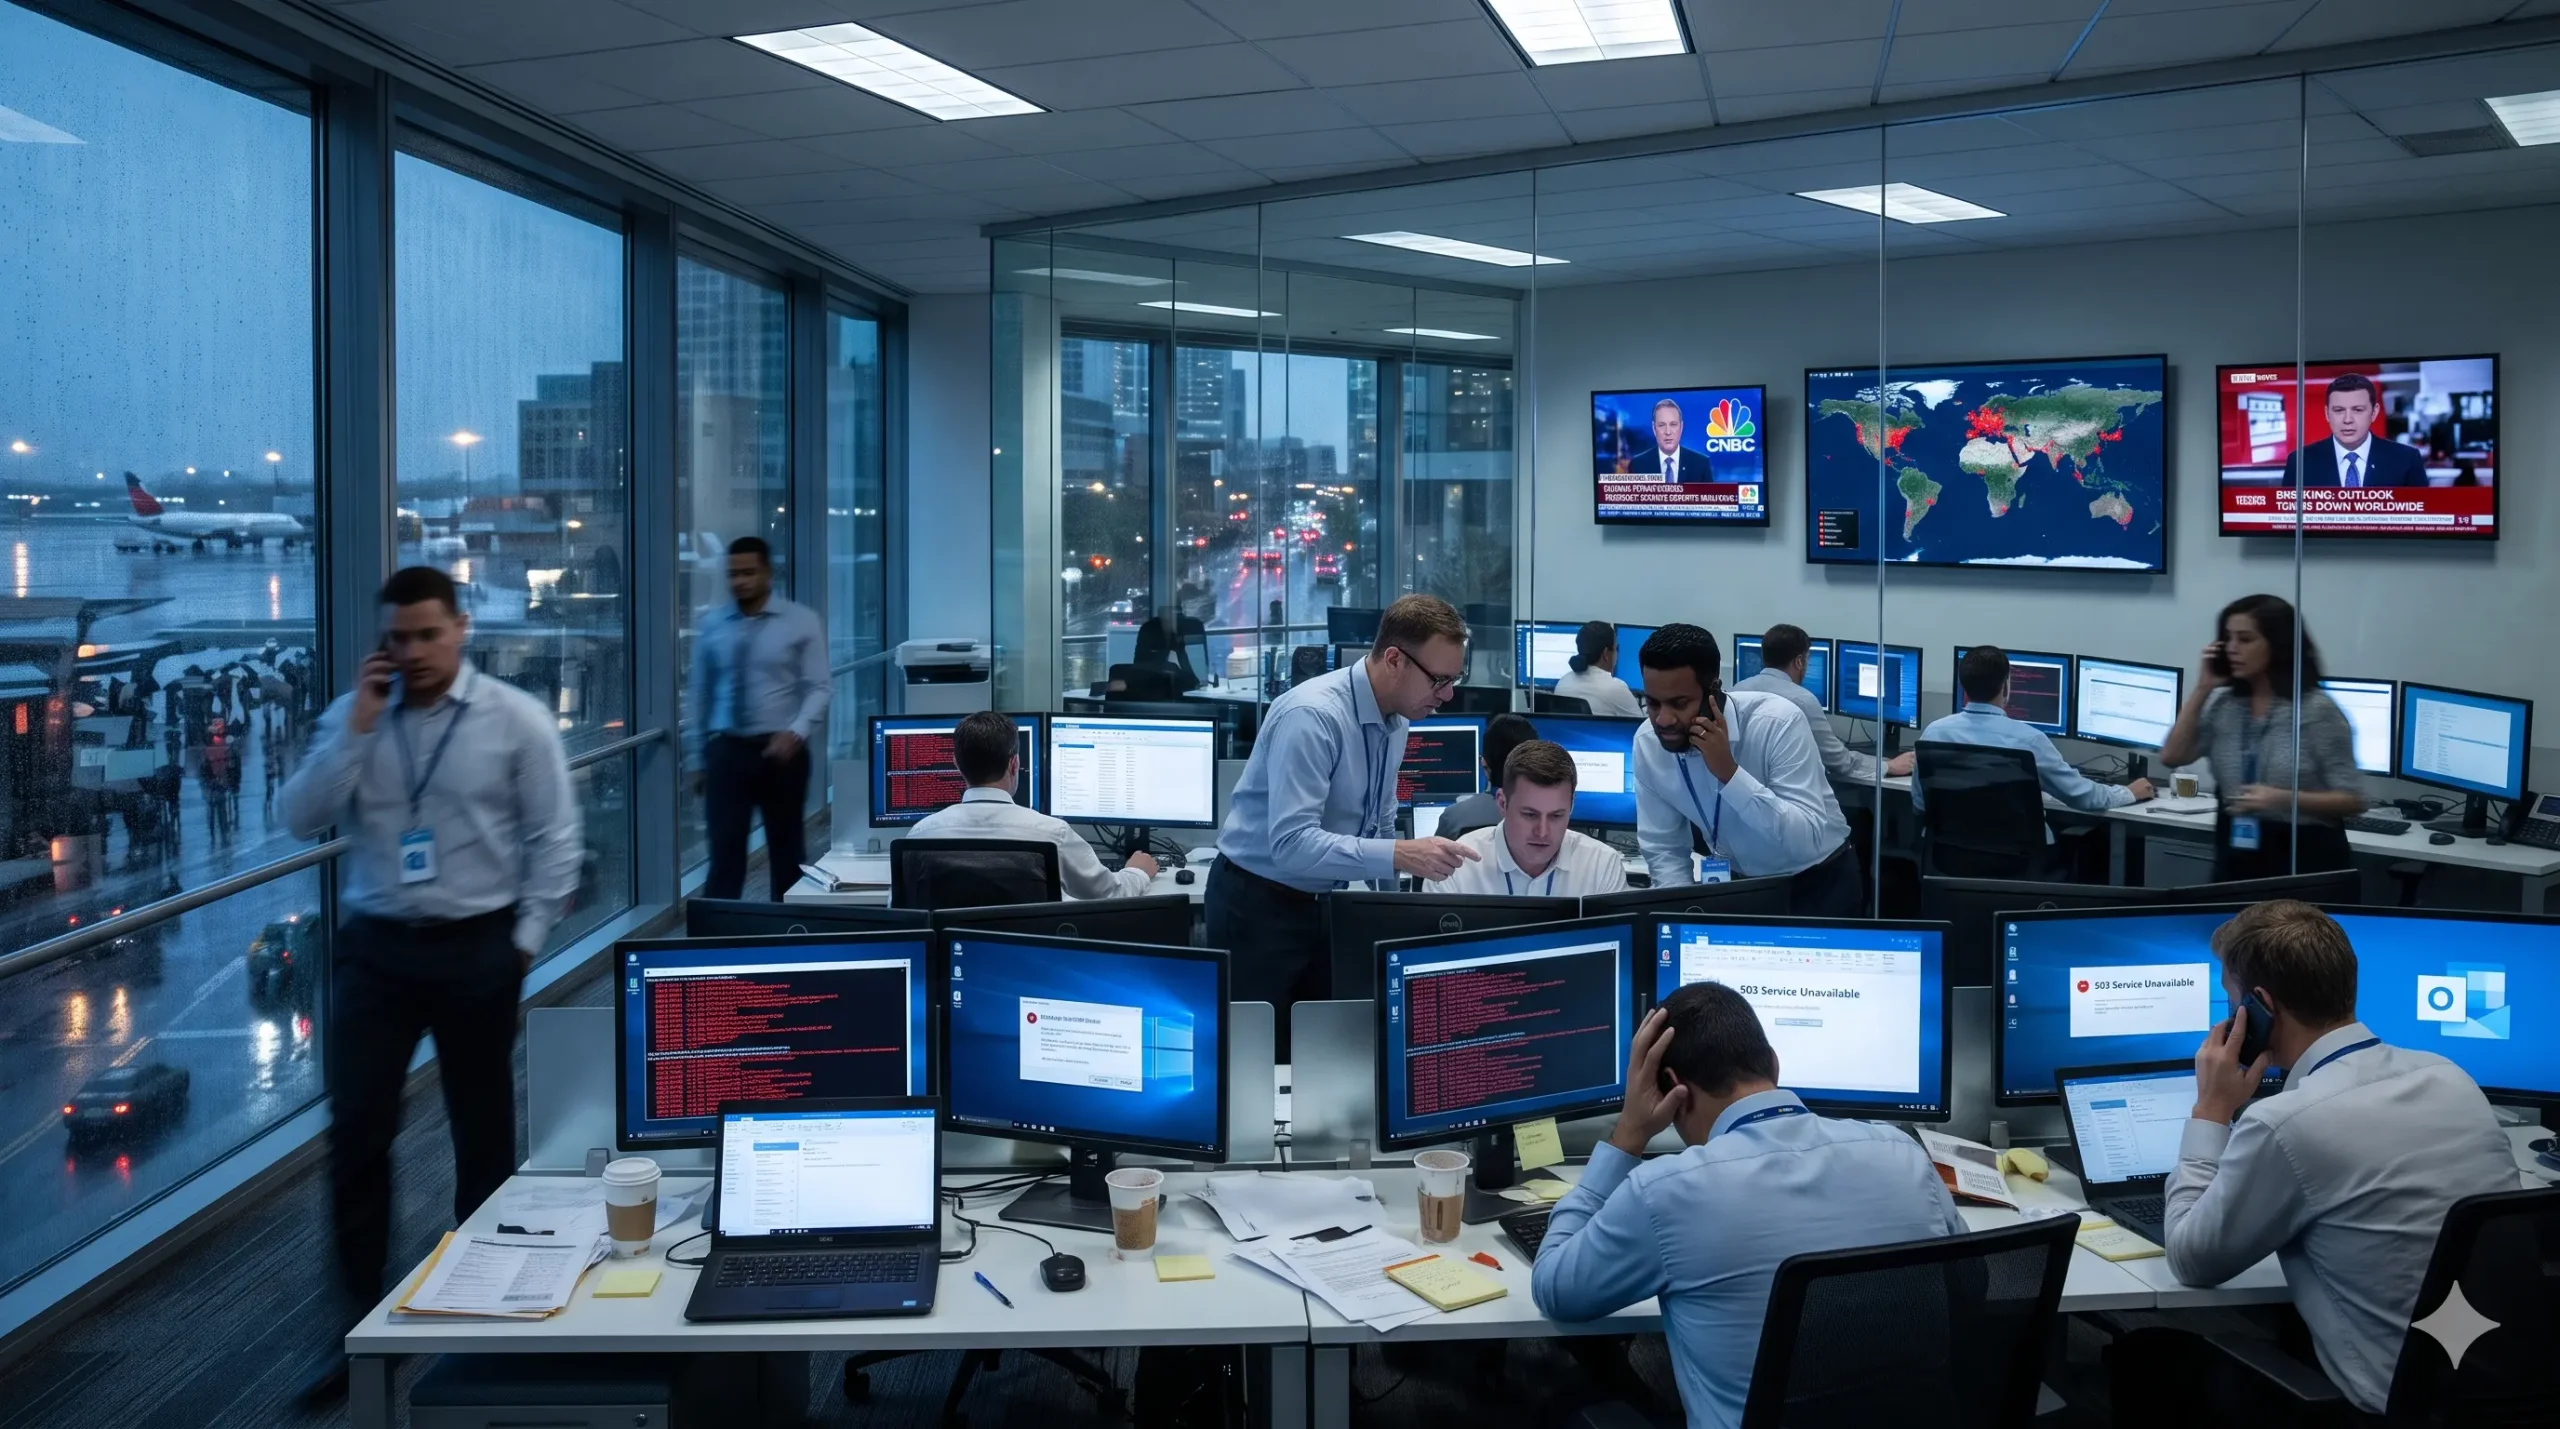
Microsoft is facing serious questions about the reliability of its cloud infrastructure after a major technical failure disrupted several of its services worldwide. What initially appeared to be a problem with Outlook and Microsoft Teams quickly escalated into a widespread outage, leaving millions of users and businesses struggling to access essential digital tools.
The disruption began on Thursday and continued for much of the day. Although the initial reports suggested that the issue was limited to the United States and other parts of the Americas, the impact soon expanded across multiple regions. Microsoft’s engineering teams worked to restore affected systems, but recovering the infrastructure proved more difficult than expected.
One Technical Problem Disrupted Multiple Microsoft Products
The outage was not limited to email and video conferencing. As the situation developed, several important Microsoft products and services became unavailable or experienced performance problems.
Outlook users faced difficulties sending and receiving emails, while Microsoft Teams users reported problems with online meetings and communication. Microsoft’s cloud-based platforms, which support business email, file storage, and document management, were also affected.
The disruption extended to newer and security-focused products as well. Microsoft’s Copilot AI assistant became inaccessible for some users, while Defender, the company’s security screening solution, also experienced problems. System administrators faced additional challenges because they could not properly access internal Intune dashboards and management features.
Some customers also reported difficulties connecting to their cloud-based Windows environments.
This situation highlighted how closely Microsoft’s products depend on shared cloud infrastructure. When one critical component experiences a failure, the consequences can spread across several services that millions of people rely on every day.
Microsoft Still Investigating the Root Cause
Microsoft has not yet provided a complete technical explanation for what triggered the incident. In its initial communications, the company said that a large number of servers had unexpectedly become unavailable.
Engineers reportedly struggled to identify the underlying problem, particularly as servers across Microsoft’s data centers continued experiencing failures. The company is investigating the incident to understand what happened and how similar disruptions can be prevented in the future.
By Friday morning in the United States, Outlook had started recovering, with some users gradually receiving delayed emails. Internet traffic monitoring company Kentik also reported signs of improvement.
Doug Madory, Kentik’s director of internet analysis, shared that Microsoft’s service traffic was beginning to return after approximately 18 hours of disruption.
Although services were gradually coming back online, the recovery process demonstrated how challenging it can be to restore large-scale cloud systems when multiple components are affected simultaneously.
Cyberattack Concerns Addressed, But Questions Remain
Another important concern surrounding the incident was whether the disruption involved malicious activity.
Microsoft stated in its latest service update that it had found no evidence suggesting that the outage was connected to a cyberattack. This announcement offered some reassurance to customers worried about potential security threats.
However, the statement does not fully explain what happened inside the company’s infrastructure. Questions remain about the technical failure, the availability of server logs, and how Microsoft verifies whether suspicious activity has occurred during a major incident.
The company will likely need to provide more transparency as businesses and organizations evaluate the reliability of its cloud services.
Another Outage Raises Reliability Concerns
This incident is particularly significant because it follows another major disruption in September, when Microsoft experienced a multi-day cloud service outage. At that time, the company identified a problem involving its core authentication configuration, which prevented users from accessing certain services.
Two major incidents within a relatively short period could increase pressure on Microsoft to improve its infrastructure monitoring, failure detection, and disaster recovery capabilities.
The Bigger Lesson for Cloud-Dependent Businesses
Microsoft’s latest outage is a reminder that even the world’s largest technology companies are not immune to infrastructure failures. Businesses increasingly depend on cloud platforms for communication, collaboration, cybersecurity, and daily operations.
When these platforms stop working, the impact goes beyond inconvenience. Employees can lose access to important documents, businesses may experience operational delays, and communication between teams can come to a standstill.
For organizations, maintaining backup communication channels, independent data backups, and alternative recovery plans is becoming increasingly important.
Final Thoughts
Microsoft’s global disruption demonstrates how a technical issue within a major cloud infrastructure provider can quickly affect millions of users and organizations. While services are gradually recovering, the bigger challenge for Microsoft will be explaining the failure, restoring customer confidence, and ensuring that a similar incident does not happen again.
As cloud technology becomes central to modern business operations, reliability is no longer just a technical requirement. It is a critical part of customer trust.